Distributed Systems · Storage · Go · Java
i read the kafka paper, then rebuilt it badly
A month of reimplementing Kafka's log layer from the design paper, and the storage engine I had to rewrite three times because I skipped the parts I didn't understand.
This is the first paper i read properly and then went and implemented. at first it felt confusing and heavy, but the more i kept going the more it made sense — mostly once i stopped trying to hold the whole thing in my head and started building one layer at a time.
so instead of just reading it, i built a simplified version from scratch.
This took me around a month, and it is the most careful work i have done so far. i didn't rush it. i went layer by layer and tried to understand what i was building instead of just making things compile. this is not a production-ready system — it is a learning implementation, and i am going to be honest about what is missing.
what this actually is
- Storage is partition-based, not replicated. each partition lives on exactly one broker, stored locally on disk.
- There are multiple brokers. partitions are assigned to brokers, a coordinator decides which broker owns which partition, and clients route requests to the right one.
- The producer side works. it can choose partitions with round-robin, key-based hashing, or an explicit partition, then send to the broker.
- The consumer side works. it polls from brokers, with consumer groups and committed offsets.
- It is mostly synchronous. producer calls broker directly, broker writes to storage directly, consumer polls directly. no real async processing or background workers yet.
- The one async-ish thing is long-polling in fetch, using wait/notify. that is not a fully async or non-blocking system.
What is still missing compared to real Kafka:
- replication across brokers
- leader/follower, or any consensus at all
- actual network communication between brokers
- persistent distributed metadata
- async processing / non-blocking APIs
So: a broker-based, partitioned, Kafka-shaped system with multiple brokers and routing. Not fully distributed, not asynchronous.
GitHub — akansha204/kofta
Paper — Kafka: a Distributed Messaging System for Log Processing
what i planned to do first
i wanted to keep it small. a single-broker implementation, not even thinking about distribution. i started with a segment-based append-only storage engine, disk reads and writes, serialization, and sequential offsets per partition.
public class LogSegment {
    private RandomAccessFile file;
    private long currOffset;

    public LogSegment(String path) throws IOException {
        this.file = new RandomAccessFile(path, "rw");
        this.currOffset = 0;
    }

    public synchronized long append(String message) throws IOException {
        long newOffset = currOffset + 1;
        currOffset = newOffset;

        Message msg = new Message(newOffset, System.currentTimeMillis(), message.getBytes());
        byte[] data = serialize(msg);

        long fileOffset = file.length();
        file.seek(fileOffset);
        file.write(data);

        return newOffset;
    }

    public Message read(long fileOffset) throws IOException {
        file.seek(fileOffset);
        int length = file.readInt();

        byte[] buffer = new byte[4 + length];
        file.seek(fileOffset);
        file.readFully(buffer);

        return deserialize(buffer);
    }
}
with a small Message class holding offset, timestamp, payload.
At that point this was one segment per partition, with no rolling and no multi-partitioning. The flow:
Producer -> LogSegment (append) -> file on disk
                    |
        message with offset + timestamp
                    |
        binary format for persistence
                    |
Consumer -> LogSegment (read) -> message from disk
Offsets are monotonically increasing identifiers for a record's position within a partition. Serialization is the binary on-disk representation. In real Kafka, offsets get resolved to physical file positions through index files before a read happens — which, as it turns out, is the part i was about to get wrong.
I was satisfied with this and i thought it would be hard to digest, so i avoided record batches, CRC validation and log recovery. That was my biggest mistake. Later i had to implement all of them anyway, and every time i added one i had to modify the storage engine again.
adding a broker layer
Next came producers and consumers working directly against a Partition:
public class Producer {
    private Partition partition;
    public Producer(Partition partition) { this.partition = partition; }
    public long send(String message) throws IOException { return partition.append(message); }
}public class Consumer {
private Partition partition;
private long curroffset = 1;
public Consumer(Partition partition) { this.partition = partition; }
public void poll(int maxMessages) throws Exception {
for (int i = 0; i < maxMessages; i++) {
try {
Message msg = partition.read(curroffset);
if (msg == null) break;
System.out.println("Consumed: " + new String(msg.payload));
curroffset++;
} catch (RuntimeException e) {
if (e.getMessage().equals("Offset not found")) break;
else throw e;
}
}
}
}Everything worked, but the design was too simple to survive contact with anything real. So i put a broker layer between producer and consumer, because Kafka is built around brokers as the core abstraction:
public class Broker {
    private Map<String, Partition> topics = new HashMap<>();

    public void createTopic(String topicName) throws TopicAlreadyFoundException, IOException {
        if (topics.containsKey(topicName)) throw new TopicAlreadyExistsException();
        topics.put(topicName, new Partition("../data/" + topicName));
    }

    public void send(String topicName, String message) throws IOException {
        if (!topics.containsKey(topicName)) throw new TopicNotFoundException();
        topics.get(topicName).append(message);
    }

    public List<Message> consume(String topic, long offset, long maxMessages) throws Exception {
        List<Message> messages = new ArrayList<>();
        for (int i = 0; i < maxMessages; i++) {
            try {
                messages.add(topics.get(topic).read(offset));
                offset++;
            } catch (Exception e) {
                break;
            }
        }
        return messages;
    }
}
Ignore the exceptions — i wrote custom ones for this project. With brokers in place, topics arrive too: a topic is a logical collection of one or more partitions, and the broker keeps an in-memory map from topic to partition. At this stage each topic was a single partition, which is a simplification i knew about and did not yet care about.
multi-partition topics
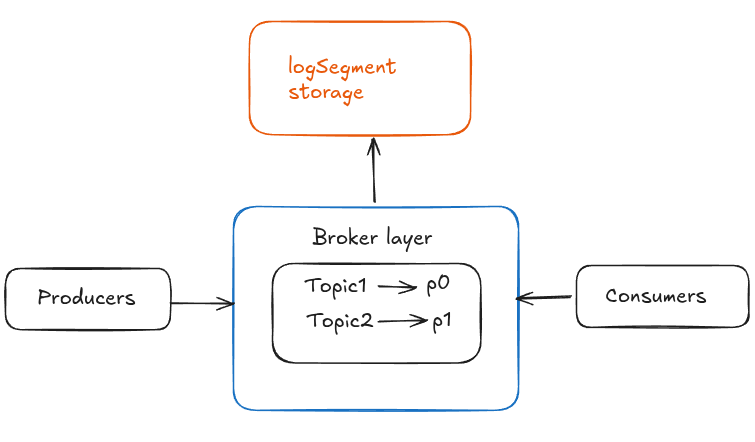
The first version: producer straight to partition. The broker layer came later.
Real Kafka has multiple partitions per topic, so that was next. It meant:
- tracking multiple partitions per topic
private Map<String, List<Partition>> topics = new HashMap<>();- tracking where to resume the round-robin
private Map<String, Integer> nextPartitionIndex = new HashMap<>();- and actually implementing round-robin on the producer side
List<Partition> partitionsList = topics.get(topicName);
int idx = nextPartitionIndex.get(topicName);

Partition partition = partitionsList.get(idx);
partition.append(message);

int nextidx = (idx + 1) % partitionsList.size();
nextPartitionIndex.put(topicName, nextidx);
which looks like this:
topic: orders (3 partitions)

p0 <- msg1
p1 <- msg2
p2 <- msg3
p0 <- msg4
p1 <- msg5
p2 <- msg6 ...
Once topics had multiple partitions, the consumer had to read from all of them, tracking offsets per partition instead of one cursor:
public void poll(int maxMessages) throws Exception {
    for (Partition p : partitionList) {
        long curroffset = partitionoffset.get(p);
        for (int i = 0; i < maxMessages; i++) {
            try {
                Message msg = p.read(curroffset);
                if (msg == null) break;
                System.out.println("Consumed: partition " + p + " offset " + curroffset
                        + " -> " + new String(msg.payload));
                curroffset++;
            } catch (Exception e) {
                break;
            }
        }
        partitionoffset.put(p, curroffset);
    }
}
I also removed the broker's dependence on consumption state at this point. In Kafka the broker is stateless with respect to consumption — it does not track consumer offsets — so holding a consumer's offset inside the broker was the wrong shape, and multi-partition topics made it obvious.
consumer groups, and the rewrite I earned
Then consumer groups, which is where the earlier shortcuts came due. The order of the work so far:
- core
LogSegmentstorage - a
Partitionabstraction over it - producer and consumer using
Partition - a
Brokerlayer added on top - multi-partition topics
- producer and consumer both modified for them
- consumer groups
public class ConsumerGroup {
    private String groupId;
    private List<Consumer> consumersList;
    private Map<Partition, Consumer> partitionAssignment;

    public void setPartitionAssignment(List<Partition> partitionList) {
        consumersList.clearAssignments();
        partitionAssignment.clear();

        int i = 0;
        for (Partition p : partitionList) {
            Consumer c = consumersList.get(i % consumersList.size());
            partitionAssignment.put(p, c);
            c.addPartition(p);
            i++;
        }
    }
}
This represents a group of consumers working the same topic. Instead of every consumer reading everything, partitions get divided between them:
- partition assignment — partitions distributed round-robin, so each partition has exactly one owner at a time
- clearing previous assignments — old partitions are released before reassigning, roughly analogous to a rebalance
- consumer owns its partitions — it only polls what it was assigned, which avoids duplicate consumption
- in-memory coordination — all of this lives in one process
- no rebalancing triggers — no join/leave detection, no heartbeat, no distributed group coordinator, no offset storage in the broker
consumers = [c0, c1]

partitions:
p0 -> c0
p1 -> c1
p2 -> c0
p3 -> c1
where the real implementation starts
Everything above was the version i was happy with. Everything below is what i added once the design started to break under complexity.
sparse index files
Earlier reads looked like this:
partition.read(offset)which is fine right up until the file is large, at which point it is very slow. The fix is a sparse index file.
In this phase the LogSegment grew a second file. Before, it had one .log file. Now it has two:
Partition
    └── ONE LogSegment (single file)
        ├── .log   actual data
        └── .idx   sparse index
A useful detail i got wrong in my own earlier notes: this is a segment-level sparse index, not the same thing as a partition-level index. In the paper those are different structures, and i had merged them in my head.
To see the shape of it, take eight messages:
msg1 = "order created"
msg2 = "order paid"
msg3 = "order shipped"
msg4 = "order delivered"
msg5 = "order returned"
msg6 = "order refunded"
msg7 = "order closed"
msg8 = "order archived"
Each message is stored in the .log file as:
[length][offset][timestamp][payload]Say each averages 50 bytes. On disk:
Position (bytes) → Data

[0]    offset=1 → "order created"
[50]   offset=2 → "order paid"
[100]  offset=3 → "order shipped"
[150]  offset=4 → "order delivered"
[200]  offset=5 → "order returned"
[250]  offset=6 → "order refunded"
[300]  offset=7 → "order closed"
[350]  offset=8 → "order archived"
Now say we write an index entry every third message — offsets 1, 4, 7:
Index File (.idx)
    Offset → FilePosition

    1 → 0
    4 → 150
    7 → 300
A consumer asking for offset 8 finds the closest smaller index entry, offset 7 at position 300, seeks there, and scans forward until it finds 8. file.seek(300). That is the whole trick.
records, batches and CRC
A record is a fancier name for a message. Record batches exist because appending one record at a time is wasteful — you append, read and checksum in batches.
public class RecordBatch {
    private long baseOffset;
    private List<Record> recordList;
    private long crc;

    public RecordBatch(long baseOffset, List<Record> recordList) {
        this.baseOffset = baseOffset;
        this.recordList = recordList;
        this.crc = calculateCrc();
    }

    private long calculateCrc() {
        CRC32 crc32 = new CRC32();
        for (Record record : recordList) crc32.update(record.toBytes());
        return crc32.getValue();
    }

    public boolean isValid() {
        return calculateCrc() == this.crc;
    }
}
RecordBatch wraps a list of records with base offsets so the segment can move them as a single unit. The CRC is there so a batch that got truncated or altered on disk is detected rather than silently read.
the api layer
With records, batches, checksums and batch read/write in place, the system needed a way to expose all of that. So i added a thin API layer on top of Partition.
- Producer:
ProduceRequest(topic, partition, messages[]),ProduceResponse(baseOffset, lastOffset) - Consumer:
FetchRequest(topic, partition, offset, limit, maxWait),FetchResponse(records, latestOffsets) - Broker:
ListOffsetRequest(topic, partition, OffsetSpec<Earliest|Latest>),ListOffsetResponse(offset)
which meant adding a few methods to storage — readFromOffsets(offset, limit), getLatestOffset(), getEarliestOffset() — and adjusting the producer and consumer to sit on them.
Worth saying plainly: this implementation has no networking. i could have added it, but i did not want to overcomplicate things, and i would rather leave it out than leave it half-wired.
multiple segments per partition
Until now one partition meant one segment file, which does not scale. So partitions became many segments:
Partition
    ├── LogSegment (baseOffset = 0)
    │     ├── 00000000000000000000.log
    │     └── 00000000000000000000.idx
    │
    ├── LogSegment (baseOffset = 100)
    │     ├── 00000000000000000100.log
    │     └── 00000000000000000100.idx
    │
    └── LogSegment (baseOffset = 200)
          ├── 00000000000000000200.log
          └── 00000000000000000200.idx
What changed:
- each segment carries a
baseOffsetmarking where it starts - segment files are named after that base offset, so they sort naturally
- each segment still owns a
.logand an.idx
A new segment is created when either condition fires:
- size-based roll —
shouldRollBySize(maxSegmentBytes) - time-based roll —
shouldRollByAge(maxSegmentAgeMs, now)
When a roll happens the current segment closes, a new one is created, and its baseOffset becomes the offset of the next incoming message.
Why it matters: it avoids enormous files, makes reads faster, lets old data be deleted in bounded chunks, and gives you something sane to base retention on.
retention
With multiple segments, deletion can happen at segment granularity. isExpiredForRetention(retentionMs, now) checks whether a segment has aged out, and if it has, the whole segment goes — .log and .idx together — and nothing reads or writes to it again.
Before: Partition → single LogSegment. After: Partition → multiple LogSegments, ordered by baseOffset.
So a read becomes: find the segment containing the offset, use the sparse index inside it, scan forward to the exact record, and if it is not there, move to the next segment.
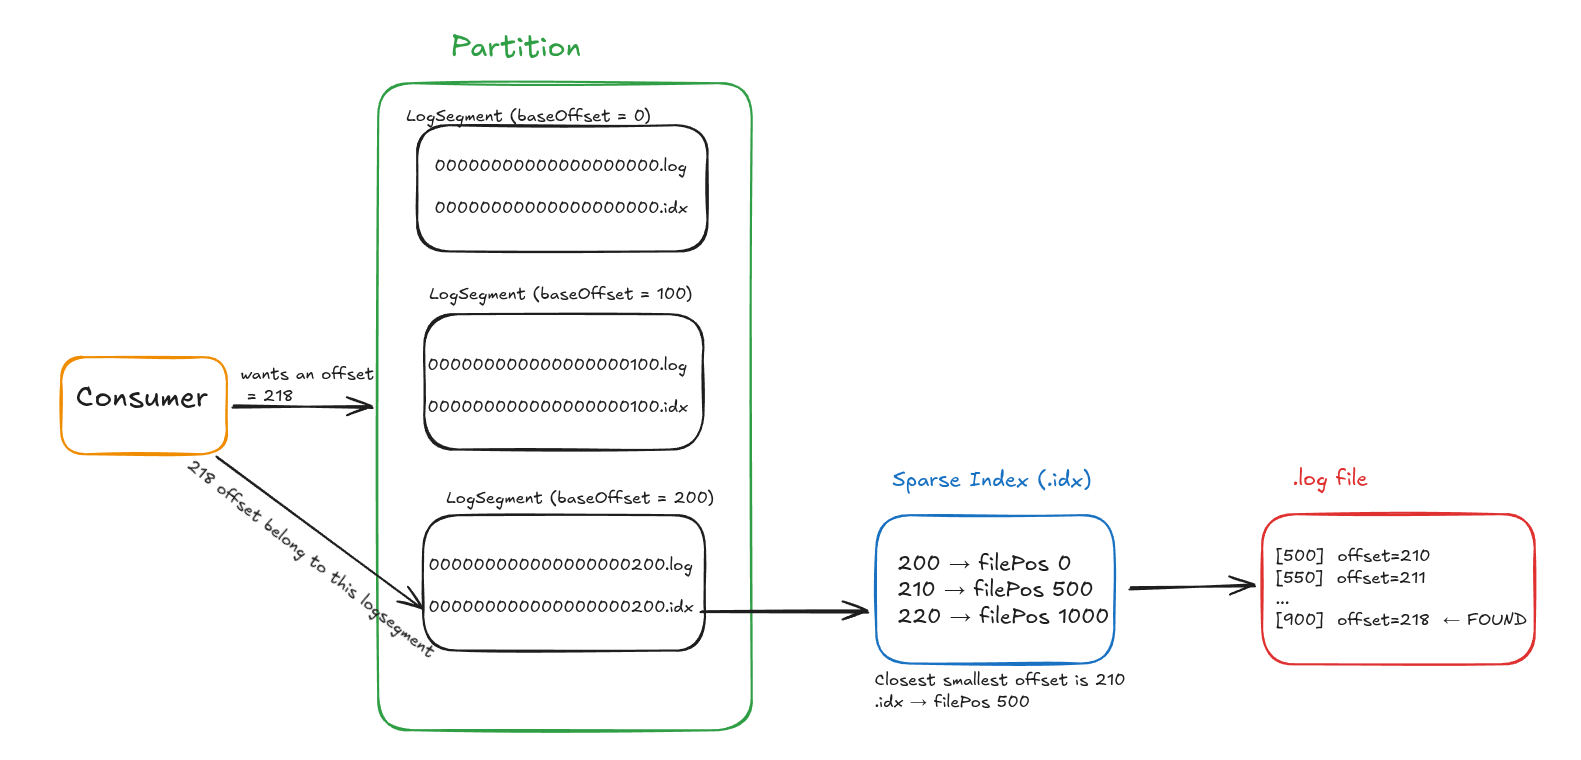
coordination for consumer groups
Up to this point consumers read partitions directly and kept their own offsets. Consumer groups make that harder, because something now has to track group membership, assign partitions, rebalance when members come and go, and remember offsets per partition.
The paper uses ZooKeeper for all of this. Instead of an external system, i built a simplified in-memory coordinator.
Each group holds:
- topic — which topic this group consumes
- partitionCount
- generation — a version number for the group, which matters for rebalancing
- members — active consumers
- assignments — which partition went to which consumer
- ownershipRegistry — which consumer is actually reading right now
- offsetRegistry — last committed offset per partition
joinConsumer(...) adds a consumer, records topic and partition count, updates heartbeat info, and triggers a rebalance.
rebalancing
rebalance(state) fires when a consumer joins, leaves, or times out:
members = [c0, c1, c2]
partitions = [0,1,2,3,4,5]

c0 → [0,1]
c1 → [2,3]
c2 → [4,5]
Partitions get spread evenly, each goes to exactly one consumer, the generation is incremented, old assignments are cleared, and ownership is adjusted.
heartbeats
heartbeat(...) keeps consumers marked alive. If a heartbeat does not arrive within sessionTimeoutMs, the consumer is considered dead. expireTimedOutMembers(...) removes them and triggers another rebalance — which is how the system recovers on its own.
assignment is not ownership
This distinction was not in my original design and only became obvious once there was more than one consumer. At first they look like the same thing, but:
- assignment means "you are supposed to read this partition"
- ownership means "you are reading this partition right now"
They are not the same, and the gap between them is where the bugs live. After a rebalance a consumer may hold an assignment it has not started reading yet, while another consumer is still reading it.
So claimPartition(...) has to succeed before a consumer starts:
- the partition is genuinely assigned to it
- the generation is current, not stale from before a rebalance
- nobody else owns it right now
And releasePartition(...) is called when it is done, or when a rebalance happens — at which point someone else is free to take it.
The part i had to think hardest about: after a rebalance, ownership is not blindly kept. Assignments are recalculated, but ownership survives only if that partition is still assigned to the same consumer. Otherwise it is dropped.
offsets
commitOffset(...) only succeeds if the consumer owns the partition and the generation is valid. readCommittedOffset(...) returns the last committed offset, which is what a restarting consumer reads from.
a multi-broker cluster
Even with partitions and consumer groups, all of this was happening inside one process. To get closer to how Kafka actually works, i extended it to multiple brokers, and introduced a cluster coordination service that tracks live brokers, places a topic's partitions across them, and routes requests to the right one.
Each broker registers itself with registerBroker(...) — broker id, endpoint, session timeout — and then sends brokerheartbeat(...) to stay marked alive. expireTimedOutBrokers(...) removes brokers that stop sending them. That is a very simple failure detector, and it is the honest kind.
When a topic is created, createTopicStaticPlacement(...) fetches the active brokers and spreads the partitions:
brokers = [0,1,2]
partitions = [0,1,2,3,4,5]

p0 → broker0
p1 → broker1
p2 → broker2
p3 → broker0
p4 → broker1
p5 → broker2
Round-robin, one broker per partition. Then routing goes through ownerBroker(topic, partition) to find the right broker for a given partition:
Producer → ClusterCoordService → correct Broker → Partition → LogSegmentAnd metadataSnapshot() returns the live brokers plus the partition-to-broker mapping — roughly what a Kafka client fetches before it starts sending anything.
what it does, and what it does not
It supports multiple brokers, distributes partitions across them, routes requests correctly, and detects basic broker failure.
It does not have:
- replication across brokers
- a leader/follower model
- automatic rebalancing after a broker failure
- distributed consensus
So this is not a distributed Kafka cluster. It is a multi-broker setup that has the right shape and none of the hard guarantees, which is roughly what a month of evenings buys you.
closing
The last layer moved the system from a single broker to something cluster-shaped. After that i tested it against a set of failure scenarios and wrote some basic benchmarks.
The full implementation, the benchmark numbers, and an honest list of what is broken are in the GitHub README.
What i would do next, in order: replication, then leader election, then making any of it asynchronous. Every one of those is a rewrite of something i thought was finished, which is probably the real lesson of this project.